For platform owners, automation operators, and incident response leads, workflow monitoring & recovery is a controlled response to automations failing silently without notice, causing lost lead data or broken reporting. The discovery session traces work between workflow logs and alert channels, agrees measurement ownership, and records the current baseline. JXING Tech then scopes the smallest useful pilot around client-owned platforms and named reviewers.
The operating case for workflow monitoring & recovery
Automations failing silently without notice, causing lost lead data or broken reporting. For a medium-sized company, that can consume management time and hide stalled work. At enterprise scale, inconsistent handling creates reporting and governance gaps. The process should be made visible before automation is introduced.
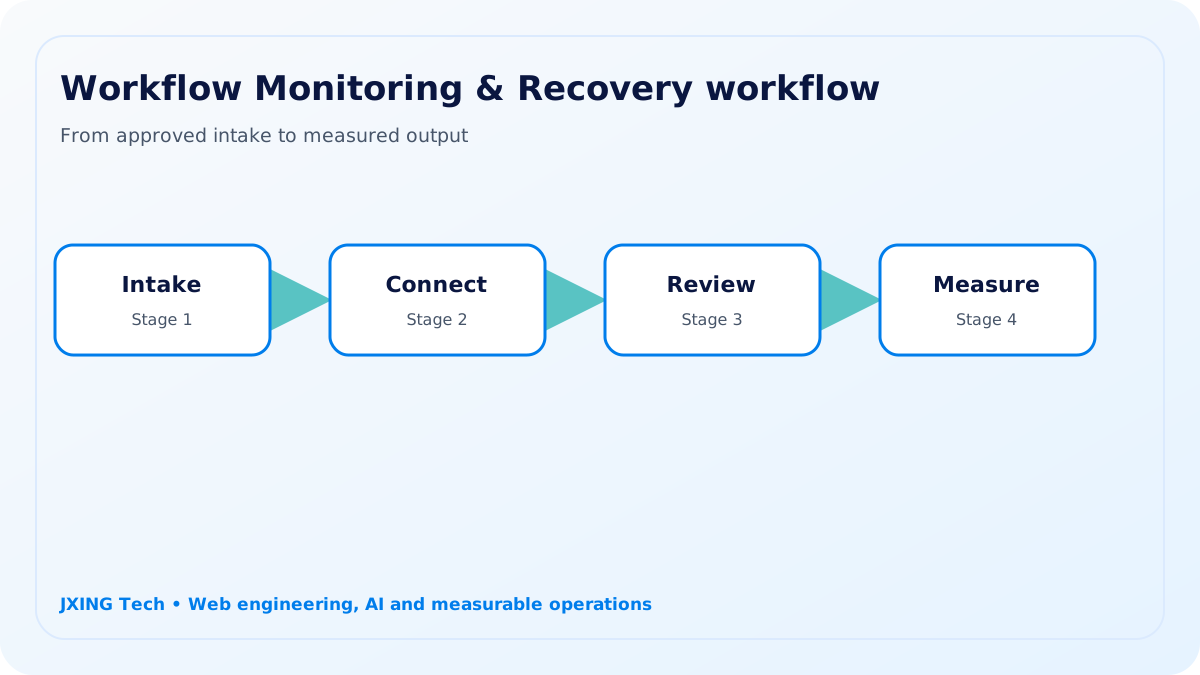
From intake to accountable action
In practical terms, the service tracks approved API webhooks, scheduled jobs, and scripts to identify monitored failures, notify team leads, and prepare technical investigation notes. Approved connections may involve workflow logs, alert channels, approved runbooks, and incident dashboards. Clear rules handle routine routing; people review exceptions, sensitive data, and outward-facing decisions.
Value for medium-sized and large businesses
A medium-sized technology team can surface monitored failures and route investigation work to a named owner. The initial objective for workflow monitoring & recovery is a measurable change in failures detected within one bounded workflow.
A larger platform organisation can coordinate alerts, runbooks, and incident evidence across multiple workflow services. Scaling workflow monitoring & recovery requires permission models, change control, support ownership, and evidence that teams can operate the new process consistently.
Where the solution can apply
software companies, financial services, e-commerce, and logistics are relevant when the same task moves between people or systems. Scope changes by sector: regulated work needs stronger evidence, while multi-site teams may prioritise consistent routing and local visibility.
Pilot scope, controls and measures
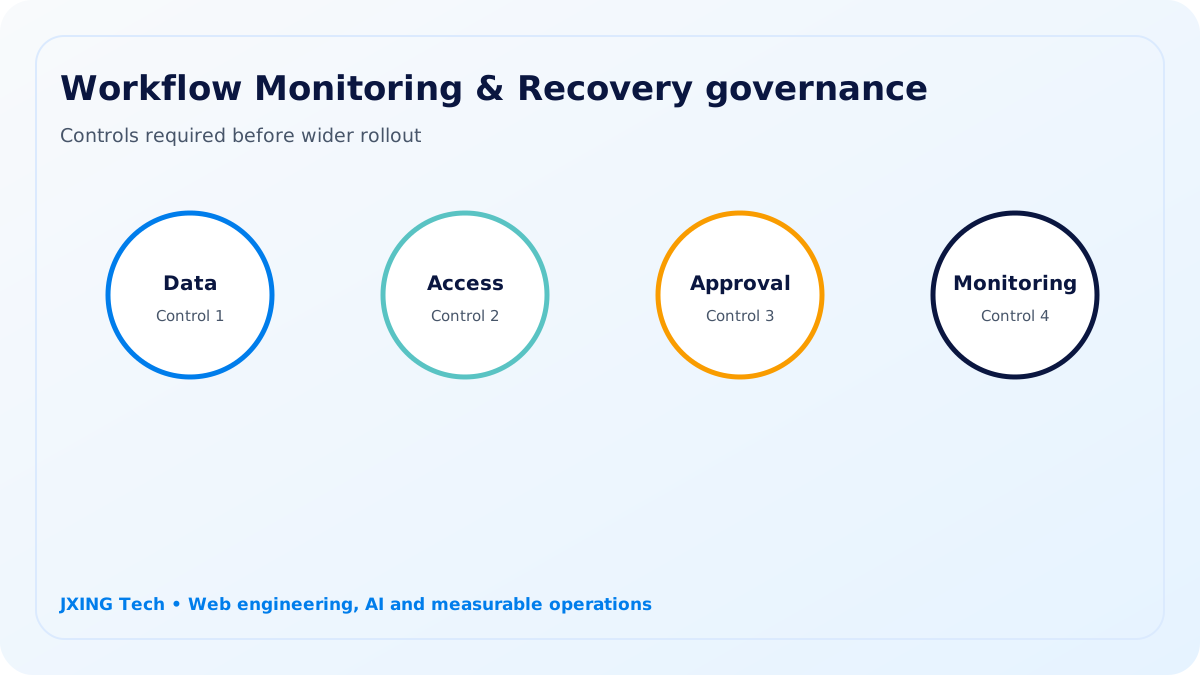
JXING Tech maps the workflow monitoring & recovery steps, system access, fallback paths, and the baseline for alerts acknowledged. The smallest maintainable integration is tested with a controlled user group before broader access.
Monitoring reduces the chance of silent failure but cannot guarantee uptime. Recovery actions follow approved runbooks and human escalation. Monitoring covers failures detected, alerts acknowledged, recovery actions reviewed, and repeat incidents; these are operating indicators, not promised commercial outcomes.
A controlled delivery path
Step 1
Trace
Follow the current workflow monitoring & recovery handoff from workflow logs into alert channels and identify waiting points.
Step 2
Configure
Set routing rules, user permissions, review thresholds, and measurement ownership.
Step 3
Observe
Run one controlled workflow while owners inspect exceptions and pilot evidence.
Step 4
Review
Use evidence from failures detected and recovery actions reviewed to choose the next delivery phase.
Target industries
Industry scope changes the evidence, access model, review authority, and response expectations for workflow monitoring & recovery.
software companies
Use case for software companies: manage handoffs through alert channels with workflow monitoring & recovery.
financial services
Use case for financial services: manage handoffs through approved runbooks with workflow monitoring & recovery.
e-commerce
Use case for e-commerce: manage handoffs through incident dashboards with workflow monitoring & recovery.
logistics
Use case for logistics: manage handoffs through workflow logs with workflow monitoring & recovery.
What the pilot includes
- Workflow Monitoring & Recovery current-state map for platform owners, automation operators, and incident response leads
- Access and data assessment for workflow logs and alert channels
- Controlled pilot measuring failures detected and alerts acknowledged
- Approved runbooks review interface for named owners
- Workflow Monitoring & Recovery QA evidence, fallback plan, and handover recommendation
Governance boundary
Monitoring reduces the chance of silent failure but cannot guarantee uptime. Recovery actions follow approved runbooks and human escalation.
Pilot measures
- failures detected
- alerts acknowledged
- recovery actions reviewed
- repeat incidents